
 Add as preferred on Google
How a Repository Health Dashboard Helped Open edX Patch certifi in 48 HoursRead More
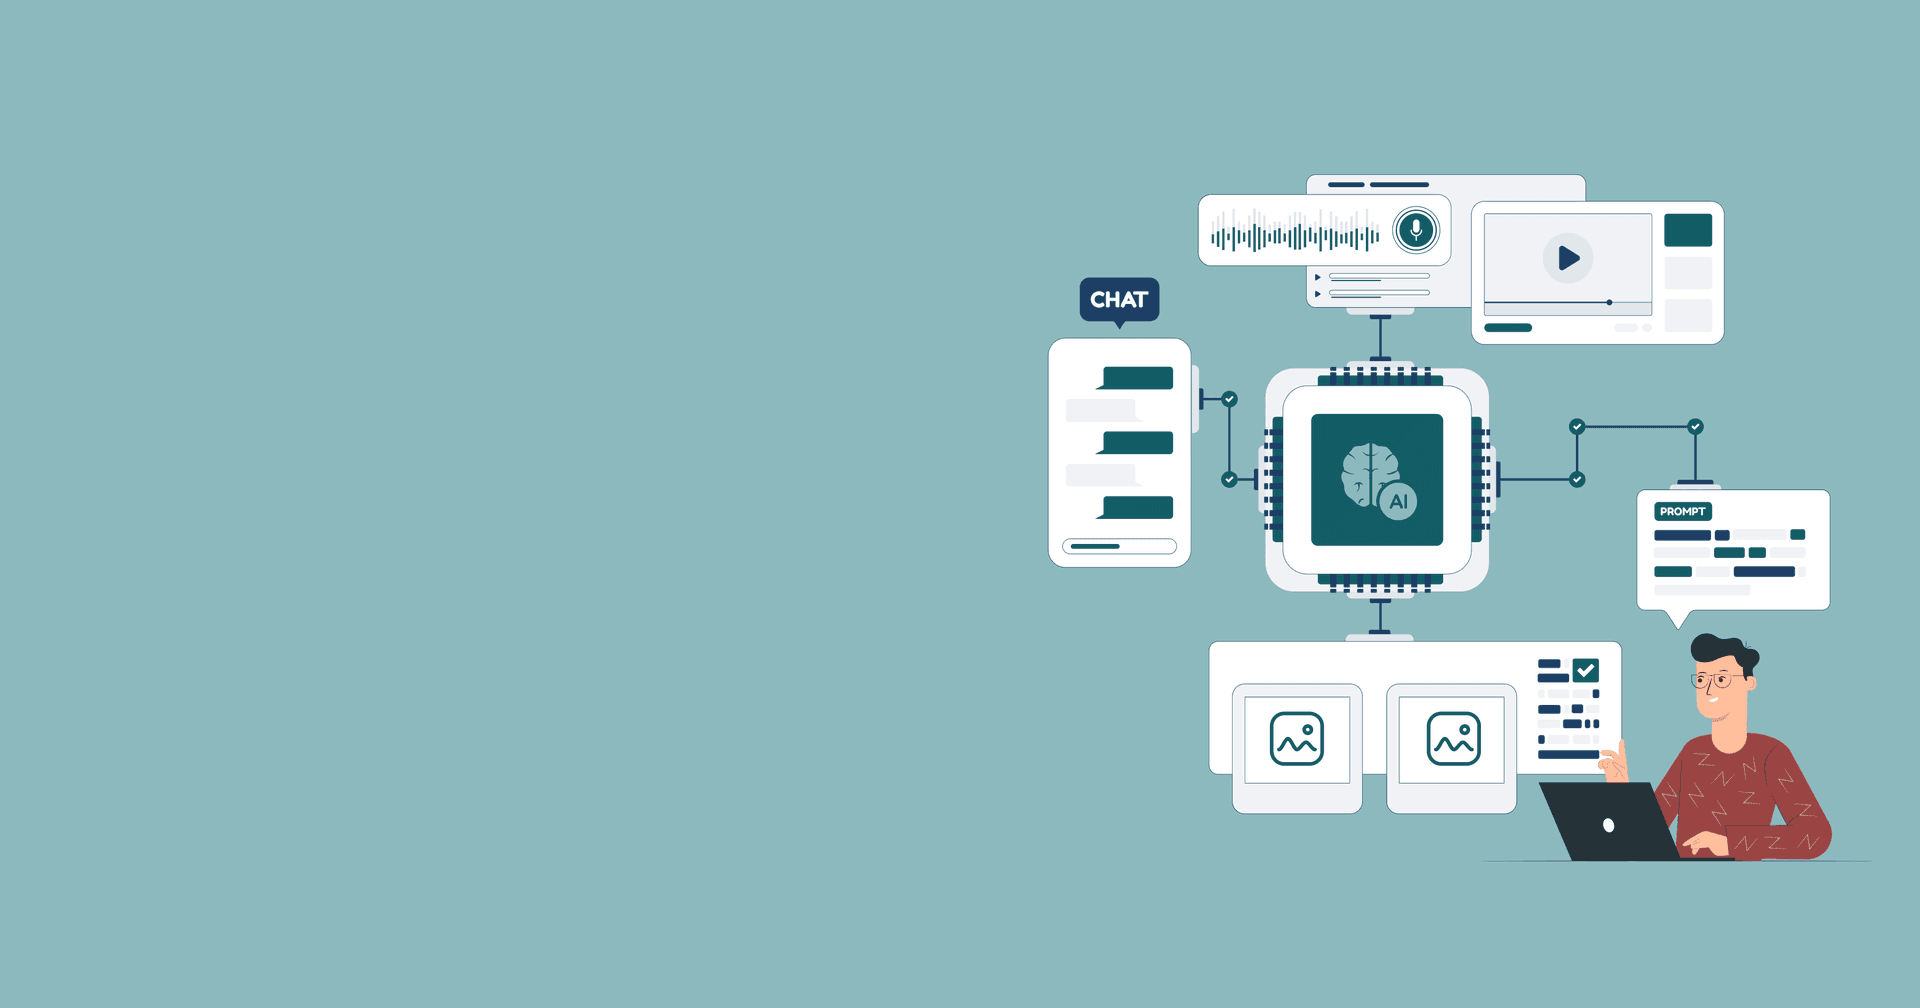
Use a generative model when the output is new content a person can review, and a predictive model when the task has fixed labels.
Bring one task and a sample of real inputs to scope a first use case.
A team that wants software to write release notes needs a different model from a team that wants to flag fraudulent orders. Release notes call for generative AI, which learns patterns in existing data and produces new text, images, code or audio. Fraud flags call for a predictive model. Picking the wrong one can cost a rebuild.
These generative AI fundamentals explain how the four main model families work and how large language models reached their late-2026 state. The article then covers where enterprises use them, how conversational AI fits in, which risks need controls before 2027 budgets are signed, and a simple rule for choosing generative or predictive models for a first use case.
Generative AI is a branch of machine learning whose models learn the patterns in existing text, images, code or audio and then produce new data that follows those same patterns. A predictive model might forecast next month's sales or classify an email as spam. A generative model writes the email.
Each output is a new sample built from what the model learned. The same request can return two different answers, and nobody can score a generated paragraph against one correct version the way a spam filter is scored against labelled emails. Teams judge output against a written standard. Factual accuracy and tone are the usual starting points.
The output is the clearest difference. Traditional machine learning returns a label or a number, such as "fraud" or a demand forecast, while generative AI returns new content such as a paragraph, an image or a function. That changes how you test it, because a fraud model can be checked against known fraud cases and a generated product description has no answer key at all.
Generative models are also more general. A sentiment analysis model predicts the emotional tone of text, and only within its predefined classes. Many businesses use sentiment analysis solutions of this kind to sort customer feedback. A large language model (LLM) given a new prompt can classify the tone of a review and then draft a reply to the customer, all without retraining, which is a lot of range for one model.
Still, a specialist model is often the better choice for one narrow, well-defined task. We'd test one first.
The boundary is blurry in places. Some traditional techniques also produce data, such as super-resolution models that sharpen low-resolution photos, but each one does a single fixed job.
Four model families cover most of what people mean by generative AI: generative adversarial networks (GANs), variational autoencoders (VAEs), diffusion models and transformer-based large language models. They differ in how they learn to generate and in the content they handle best. Model names change every few months. The families change far more slowly, which makes them the better starting point for a product decision that has to hold through 2027.
| Model family | How it generates | Typical output | Best for | Main caveat |
|---|---|---|---|---|
| GANs | A generator and a discriminator train against each other | Images, synthetic data | Sharp images in a narrow visual domain | Training can become unbalanced |
| VAEs | Sample from a learned probability distribution, then decode | Variations of existing data | Smooth, controllable variation | Images are often softer than GAN or diffusion output |
| Diffusion models | Remove noise step by step until an image appears | Images, video | High-quality images from text prompts | Many denoising steps per output, which costs more compute |
| Transformer-based LLMs | Predict the next token using attention | Text, code | Writing, summarizing, coding, chat | Can state false information confidently |
A GAN trains two neural networks against each other. The generator creates samples. The discriminator estimates whether each sample came from the real training data or from the generator, and its verdicts teach the generator to produce samples that are harder and harder to tell apart from real ones. The approach dates from a 2014 research paper.
A GAN trained on thousands of photos of one product line, say, can produce new product shots in the same style.
GANs fit narrow visual domains where sharp output matters. They're hard to train, though. The two networks must stay balanced, and a generator that finds a few outputs the discriminator accepts can keep repeating them instead of covering the full variety of the training data.
A VAE compresses each input into a short list of numbers, called a latent space, and learns a probability distribution over that space. To generate, it samples a point from the distribution and decodes it back into full data. The sampling adds controlled randomness. Outputs therefore resemble the training data without copying any single example.
A VAE trained on normal machine sensor readings can generate realistic new readings, which is handy when you need data for testing a monitoring dashboard.
VAEs fit tasks that need smooth, controllable variation of existing data. Fine image detail is harder for them. Generated images are often softer than GAN or diffusion output, which limits VAEs for photorealistic work such as product photography or realistic faces.
A diffusion model turns random noise into an image in many small steps. During training it sees real images gradually corrupted with noise and learns to reverse each step, and generation simply runs that process the other way, starting from pure noise and removing a little at a time until a coherent picture appears.
A text prompt such as "a red bicycle against a brick wall" can guide every denoising step. The picture that emerges matches the description.
Diffusion models fit high-quality image and video generation from text descriptions. The cost is compute. Because generation runs through many steps, each output takes more computation than a GAN's single pass, and that adds up when a team generates images in volume.
Text comes out one token at a time. A transformer-based LLM predicts each next token from everything that came before it, where a token is a word or part of a word. The transformer design, introduced in a 2017 research paper, relies on attention, which means that when the model processes each token it weighs every other token in the input by how relevant it is.
Attention is what links "it" to "server" in "The server crashed because it ran out of memory". Transformers also process a whole sequence in parallel. That made training on large text collections practical, and our guide to transformer architecture components covers encoders, decoders and multi-head attention in more depth if you want the details.
Give an LLM a 20-page supplier contract and it can return a one-paragraph summary with every renewal date listed.
LLMs fit writing, summarizing, coding and question answering, and many current models also accept images as input. Accuracy is their problem. An LLM predicts plausible text, so it can state something false in the same confident tone it uses for something true.
It took less than a decade for large language models to go from a research architecture to multimodal products. Two trends stand out for teams choosing a model. Smaller models caught up with larger ones, and open-weight models, whose trained weights anyone can download and run on their own infrastructure, closed in on closed ones.
As of October 2026, Arbisoft's comparison of the best LLMs in 2026 and what to expect in 2027 lists OpenAI's GPT-6 Astra and Anthropic's Claude Fable 5.1 among the leading closed models. Mistral Large 4, DeepSeek V4 Pro, Qwen3.6-27B and Muse Spark Open lead the open-weight group. For 2027, the same comparison expects flagship prices to rise and open-weight models to keep reaching trillion-parameter scale.
A ranking like this is a snapshot. Plans built around the model family and the task hold up longer than plans built around a model name.
Conversational AI is the category of systems that hold a dialogue with people, such as the chatbots on support pages and the voice assistants built into phones and cars. Generative AI is one technology inside them. Older chatbots matched a user's request to a scripted dialogue tree and returned a fixed answer. An LLM-based assistant writes each reply from the conversation so far and can handle questions nobody scripted.
The price of that flexibility is control. A scripted bot never invents a refund policy. An LLM-based assistant can, unless its answers are grounded in approved documents and checked. Our view is that support bots, including AI chatbots for ecommerce customer support, work best as a mix of scripted flows for actions such as order changes and returns and generated answers for open questions about products and policies.
Every detail a prompt leaves out is a detail the model has to guess. The prompt is the instruction a generative model works from, and a useful one states the task, the context, the audience and the output format. Compare two prompts for the same job.
The first prompt leaves the length and the reader open, and the result usually needs heavy rewriting. The second sets both. Its first draft lands much closer to usable. The same principle holds for image and code prompts, and techniques such as iterative refinement are covered in our guide to crafting better prompts.
The best results come where people already write first drafts of text or code and someone reviews them before use. Typical uses include:
Arbisoft's own coding assistant is one example. The CodeKer case study describes an AI-powered alternative to platforms like Phind, GitHub Copilot and ChatGPT Plus, built in-house to remove the risks of external paid tools and keep Arbisoft's proprietary code from being exposed. CodeKer identifies coding issues and offers test case support.
The lesson for other teams is about data. When the input is confidential source code or customer records, where the model runs and who can see the prompts matter as much as output quality.
Some sectors add their own constraints. Learning platforms are one, and our article on generative AI in enterprise learning management systems covers where it helps there and where it falls short.
Confident factual errors and biased output are the risks of generative AI closest to everyday product work, while deepfakes and misinformation at scale reach well beyond the product itself. Each needs a control before a model reaches customers. In the EU, some of those controls are now legal duties.
An LLM can answer "Berlin" when asked for the capital of France, in the same tone it uses for correct answers. It can also miss context. Ask for a chocolate no-bake cake recipe and a model may hand back an ordinary baked cake recipe, one that matches the keywords and ignores the one thing the person actually asked for.
Some errors come from how models read text in tokens instead of letters, which explains why LLMs can't count the r's in strawberry. Grounding answers in a company's own documents and reviewing outputs both reduce these errors. Neither removes them.
Biased training data can produce biased output, sometimes worse than the data itself. A support assistant trained mostly on conversations with one customer group may serve other groups less well. Averages hide the gap. Testing outputs group by group before release lowers the risk, and our article on building fair machine learning models shows how to run those bias tests and tie them to release decisions.
Generative models can produce realistic video and audio of real people. The US Government Accountability Office's 2020 Science and Tech Spotlight on deepfakes says they "can depict someone appearing to say or do something that they in fact never said or did" and calls them tools that can be used for exploitation and disinformation. Cheap, fast generation also makes fabricated text and images easier to spread.
Disclosure is now a legal duty in the EU. Under the EU AI Act's Article 50 transparency rules, which apply from 2 August 2026, providers of generative systems must mark output in a machine-readable format, and deployers who publish a deepfake must disclose it. Generative systems already on the market before that date have until 2 December 2026 to add the marking.
The Digital Omnibus on AI, Regulation (EU) 2026/1744, also moved the deadline for standalone high-risk systems, such as those used in employment and credit decisions, to 2 December 2027. Teams with EU users should treat these dates as 2027 planning inputs and ask legal and security specialists to review any use case that touches personal data or public-facing content.
Fixed labels point to a traditional predictive model. If accuracy can be measured against those labels, as with fraud flags or demand forecasts, that's the right tool. A generative model is the better fit when the output is new content, such as drafts, summaries, code or images, and a person can review it before anyone relies on it.
Many products need both. A support tool might use a classifier to route tickets and an LLM to draft the replies.
Our view is that a first generative AI project should be internal and easy to check, such as summarizing meeting notes for one team, because errors stay inside the company while the team learns what good output looks like. The team writes that standard down before building and tests several specific prompts against it. Track one number. It's the share of outputs that pass review without edits, and scaling makes sense once that share holds steady over a few weeks of real use.
A GAN learns through competition between a generator and a discriminator, and the generator improves each time the discriminator catches a fake. A diffusion model has no opponent. It learns to remove noise in small steps and builds an image gradually from random noise, which usually takes more computation per image than a GAN's single pass.
LLMs read text as tokens, which are whole words or word pieces, and the individual letters inside a token are often invisible to the model. Counting the r's in "strawberry" can trip it up for that reason. Tasks that need exact answers are better checked by code or a person.
ChatGPT is both. It is a chatbot, which makes it conversational AI, and the replies it writes come from generative large language models. Older scripted chatbots were conversational without being generative.
Training from scratch is rarely needed. We'd start most business use cases from a pre-trained model and adapt it through prompts, retrieval from company documents or fine-tuning. Reusing what a model learned in earlier training cuts computing costs, while training from scratch needs large datasets and large compute budgets.
A feature that produces drafts or generated code is a candidate for generative AI. A feature that labels or forecasts usually belongs to a predictive model. For a 2027 plan, the safer first step is one internal use case, reviewed by people against a written standard, with the pass-without-edits rate tracked from the first week.
Arbisoft's generative AI development services cover consulting, model fine-tuning and optimization, integration and proof-of-concept development, which suits a team that wants to test one use case before committing budget to a full product. Bring the task and a sample of real inputs to the first conversation.
...Loading Related Blogs
Trusted by top platforms for our transformative solutions and exceptional results:










