
 Add as preferred on Google
How a Repository Health Dashboard Helped Open edX Patch certifi in 48 HoursRead More
Deep learning improves credit scoring only on transaction, text or network data that gradient boosting cannot use, and it needs separate fairness and explainability testing.
Pilot one data type against the baseline, and set success thresholds with risk and compliance teams before the pilot starts.
Lenders that hold transaction histories, application text or borrower-network data face a practical decision: will deep learning beat the logistic regression or gradient boosting scorecards they already run? Errors in either direction are costly. A model that underestimates risk loses the lender money, and one that overestimates it denies credit to good borrowers.
Deep learning credit scoring can improve accuracy on sequence, text and network data. Fairness and explainability depend on testing and governance, and the model type does not supply them on its own. This guide covers which architecture fits which data, an eight-step build process, fairness and explainability checks, and when to stay with gradient boosting.
Logistic regression and tree-based models work well on a small set of tabular features, but they cannot read transaction sequences, free text or borrower networks directly. Early models used logistic regression, a type of statistical model. Logistic regression predicts the probability that a borrower will fail to repay a loan. It looks at a few key numbers, such as:
Logistic regression is transparent. It clearly shows how each factor affects the final score. For example, if a borrower uses most of their available credit, the model shows that this increases the chance of default. Loan officers can see exactly which inputs matter.
This simplicity is useful but has limits. Logistic regression assumes relationships between variables are linear and additive. Financial behavior is more complex. Two borrowers with the same income can act very differently. One may have steady work and manage debt carefully. Another may have irregular work and struggle with payments. Simple models cannot see these differences.
To improve predictions, lenders started using tree-based models like random forests and gradient boosting machines. These models handle nonlinear relationships, meaning the effect of one factor can depend on the value of another. They also handle interactions between variables, where multiple factors together influence risk. Tree-based models work well with structured data, like numbers in a table.
Over time, lenders began collecting richer data, such as:
Traditional models cannot fully use these data types. As finance became more digital and interconnected, lenders needed methods that could analyze large and complex datasets. Deep learning models are built to learn from these data types directly.
Deep learning credit scoring uses transaction sequences, unstructured application text and borrower-network data, along with the standard tabular data from credit bureaus. These models learn patterns directly from raw inputs, so they suit data that is large, sequential, relational or unstructured.
Every purchase, card swipe and online payment adds to a borrower's transaction history. These histories show patterns such as:
Sequence models can pick up shifts in this history, such as heavier use of credit lines in the months before missed payments. Traditional models often reduce the history to averages or totals, which can hide those early signs.
Loan applications and financial disclosures often contain free text that explains what numeric fields cannot, for example:
Natural language processing models turn this text into numerical features, so the context a borrower gives can feed into the risk prediction.
Borrowers are connected through shared accounts, co-signers and common employers, and a default can affect others in the same network. Graph neural networks map these connections and find groups of borrowers with similar risk, which a model that scores each applicant in isolation cannot see.
Engineering partners like Arbisoft build deep learning pipelines for these data types with explainability and fairness checks built in.
The eight steps below take a deep learning credit scoring model from a clearly defined prediction target to a monitored production service, in the order teams usually run them.
The first decision is the label, meaning the outcome the model predicts. Common choices include:
If the label is unclear, the model will be unreliable, because it learns to predict an outcome the business never defined.
The label also carries a selection problem. Repayment outcomes exist only for applicants who were approved, so the training data underrepresents the applicants the old policy declined. Teams should either correct for this with reject inference methods or state the limitation clearly when validating the model.
Credit scoring is only as good as its data. A strong pipeline collects, cleans, and organizes data so it can feed a model.
Data sources:
Pipeline steps:
Use ETL and orchestration tools such as Apache Airflow or Apache Spark to automate ingestion and cleaning. Always apply encryption at rest and in transit.
Deep learning models do not understand raw tables or text. You must represent data in ways the model can learn from.
For example, instead of storing only "12 late payments", store the sequence [on-time, late, on-time, late, late]. The order shows the pattern.
Each data type has architectures built for it, so the choice follows from the data the lender actually holds.
Training teaches the model to recognize risk patterns.
Frameworks like TensorFlow/Keras and PyTorch Lightning provide utilities for handling imbalance, calibration, and dropout efficiently.
Accuracy alone is not enough. Use multiple checks:
Fairness metrics to use in practice: Equal opportunity, demographic parity, and adverse impact ratio. Libraries like AIF360 and Fairlearn can automate these checks.
Once tested, the model must work in real systems.
Common tools include FastAPI or Flask for serving, Docker and Kubernetes for scaling, and MLflow for model versioning.
Borrower behavior changes with the economy. A model that works today may drift tomorrow.
Each retrained model should go through the same fairness and validation checks as the first release before it replaces the live model.
Deep learning is worth it when a lender has transaction sequences, application text or borrower-network data that gradient boosting cannot use directly. With only a few bureau and income features, gradient boosting usually remains the stronger default.
There is published evidence for deep models. Albanesi and Vamossy's 2019 NBER working paper "Predicting Consumer Default: A Deep Learning Approach" found their deep learning model consistently outperformed standard credit scoring models while using the same data. That is one study, so it justifies a test on a lender's own portfolio and does not guarantee the same result elsewhere.
A practical decision rule:
These deep learning techniques can be extended to other enterprise deep learning applications, helping organizations turn complex data into actionable insights.
Generate a decision-level explanation for every score, and test outcomes across borrower groups before launch and after. In the US, explanations are also a legal requirement. The CFPB's Circular 2022-03 (2022) states that ECOA and Regulation B require creditors to give applicants statements of specific reasons for adverse action, and that these requirements apply equally to all credit decisions regardless of the technology used to make them, including complex algorithms. Other jurisdictions have their own rules, so lenders should have compliance or legal counsel review their notices.
Three explainability methods are common:
Bias can occur even without explicit gender or race data, because other variables act as proxies. Fairness testing compares performance across subgroups with metrics such as:
Choosing deep learning does not make a model fair by itself, so any gap found in testing needs mitigation during preprocessing, training or calibration.
Around the eight build steps sits a governance and release sequence that starts with a baseline and ends with monitored deployment.
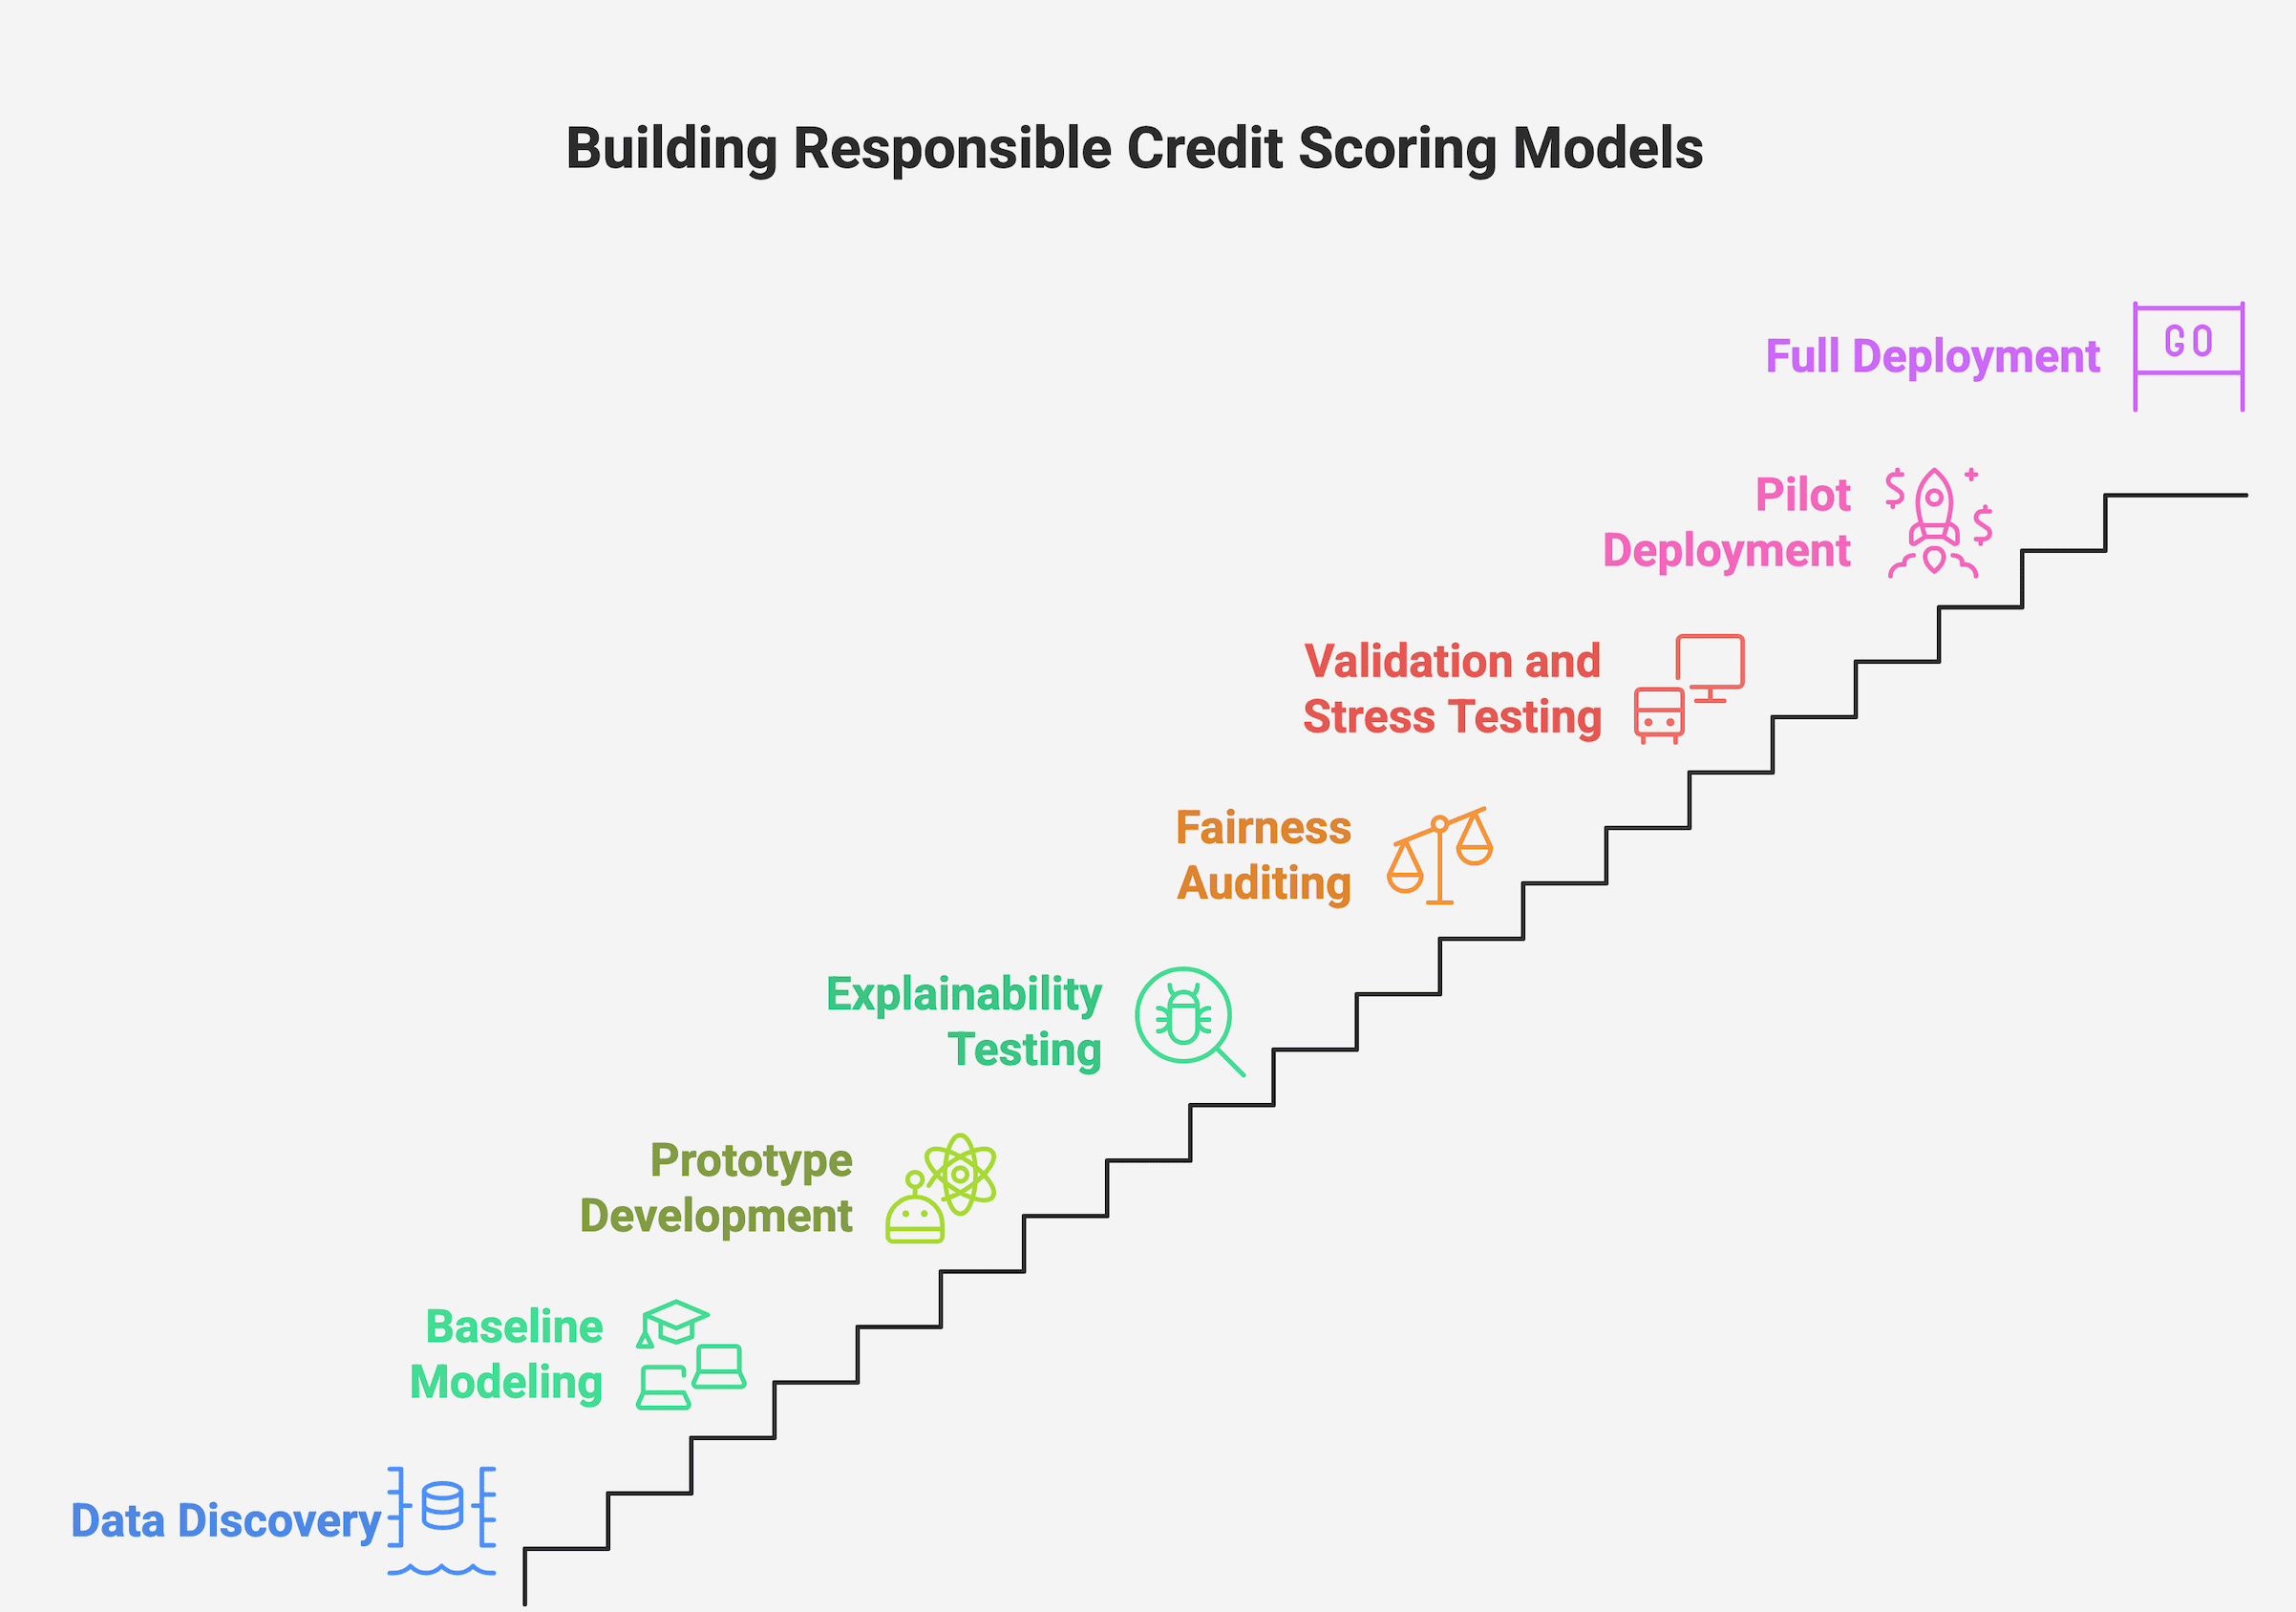
The deep model should not move past pilot until it beats the baseline and passes fairness and explainability reviews.
Success is measured on business, fairness and stability outcomes, alongside technical accuracy. A credit scoring model has earned its place in production when it passes checks like these:
Agree on the threshold for each check before the pilot starts, so results are judged against targets set in advance.
Keep a gradient boosting baseline and add deep learning only where transaction, text or network data show measurable lift on out-of-time data. Deep learning can improve accuracy on those inputs, but it does not make decisions fair or explainable by itself. Release depends on fairness testing, adverse action reason codes and human oversight.
The next decision is the pilot. Pick one data type, such as transaction histories, build a deep model for it and compare it against the baseline on the same holdout. If it wins and passes the fairness and explainability reviews, move on to the next data type.
To scope a credit-risk model assessment or pilot, talk to Arbisoft's AI team about your data and current scorecards.
Yes. The CFPB has said that ECOA and Regulation B adverse action requirements apply equally to all credit decisions, whatever technology produced them. A lender using a deep model must still give each declined applicant specific, accurate reasons. Compliance counsel should review the reason codes and notice templates before launch.
Start with feature attributions such as SHAP values for that applicant's score, and rank the factors that pushed it toward a decline. Map the top factors to plain-language reason codes, such as high credit utilization. Then check that each stated reason is accurate for that applicant and is not a generic, model-wide pattern.
It can be. The NBER study by Albanesi and Vamossy found that a deep model beat standard credit scoring models on the same data. On small tabular datasets, gradient boosting is often just as accurate and easier to explain, so the reliable test is to compare both on the same out-of-time holdout.
No. Choosing a deep model does not change fairness on its own. Variables that correlate with protected characteristics can act as proxies and carry bias into any model, deep or simple. Fairness depends on testing outcomes across borrower subgroups and applying mitigation in preprocessing, training or calibration when gaps appear.
Declined applicants never received a loan, so their repayment outcome is unknown, and the training data reflects only the old approval policy. This selection bias can make the model less reliable for applicants similar to those the old policy declined. Reject inference methods estimate their likely outcomes, and any remaining limitation should be documented during validation.
...Loading Related Blogs
Trusted by top platforms for our transformative solutions and exceptional results:










