 Add as preferred on Google
Build vs Buy vs Open Source for EdTech Platforms: How to DecideRead More
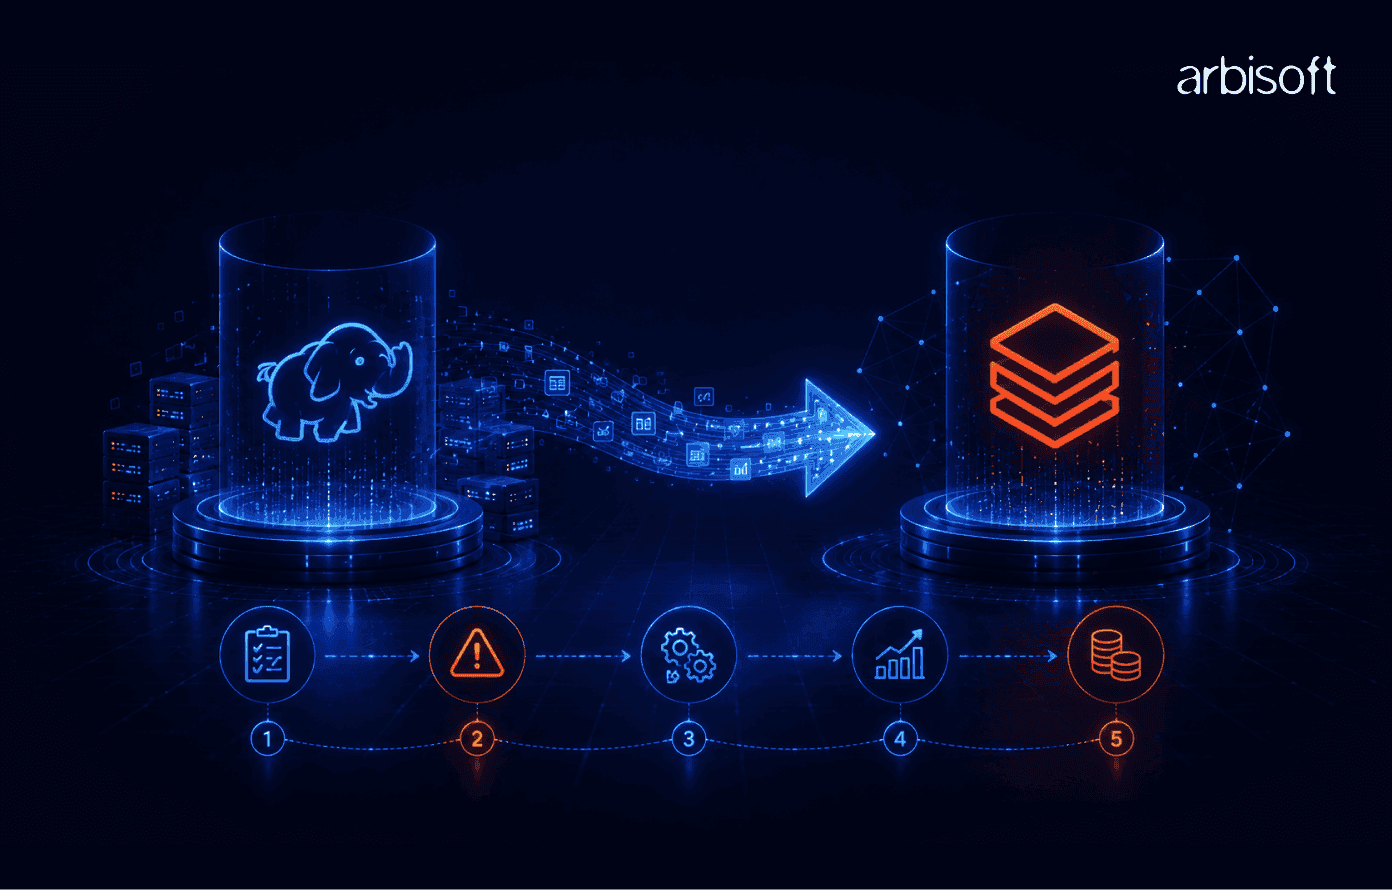
A Hadoop to Databricks migration only ends when the old cluster's data, jobs, controls, contracts, and costs are all closed.
Gate every wave on signed evidence from engineering, business, security, operations, and finance before spending more.
A Hadoop to Databricks migration is not complete when Spark code runs on the new platform. A production estate combines Hadoop Distributed File System (HDFS), Hive metadata, Spark or MapReduce execution, Yet Another Resource Negotiator (YARN), schedulers, security controls, monitoring, and operational knowledge. A migration can look complete while reports, feeds, retention obligations, or support procedures still depend on the old cluster.
Treat the program as a gated Hadoop modernisation and retirement effort. This guide focuses on the evidence needed to migrate and decommission Hadoop safely.
The first control in a Hadoop migration assessment is a source-state map, not a target-platform proof of concept. Scope, sequence, risk, and cost all depend on knowing which data, jobs, consumers, controls, and service commitments exist today.
Build an inventory that connects technical objects to business outcomes. For data, record HDFS path, format, partitioning, file count, volume, change rate, retention, owner, consumers, and whether files remain mutable. For Hive, capture databases, tables, views, locations, SerDes, functions, properties, grants, owners, and metastore version.
Workload records should include repository, language, runtime and libraries, YARN queue, schedule, retries, inputs, outputs, checkpoints, secrets, consumers, service-level agreement, recovery objectives, and named approver.
Discovery should combine HDFS listings and fsck reports, metastore queries, scheduler exports, Spark history logs, YARN history, network flows, audit logs, code search, and interviews. Hidden dependencies often sit outside the obvious platform boundary: hard-coded hdfs:// paths, JDBC clients, shell scripts, unmanaged JARs, keytabs, local edge-node files, and teams reading outputs without owning the producing job.
Require a versioned estate register, dependency graph, owner-gap list, lineage, service catalogue, and signed list of unknowns. An unknown owner is a risk, not evidence that an asset is unused.
Use one disposition vocabulary across the program:
Standard Spark SQL jobs with supported formats, limited dependencies, and reliable tests may be rehosted. Jobs tied to HDFS locality, native libraries, stateful checkpoints, small-file patterns, or legacy SQL behavior may need refactoring. Home-grown schedulers may be replaced. Retirement requires consumer evidence.
Estimate effort from the disposition and its drivers: code change, data movement, metadata remediation, integrations, testing, security classification, recovery needs, and number of environments. Every workload needs a documented rationale, approver, assumptions, and reclassification trigger.
The baseline must represent the cost of delivering today’s service, not only the hardware bill. Include servers, storage, network, facilities, cloud or colocation charges, subscriptions, support contracts, backup, monitoring, security tools, software licenses, platform engineering, patching, incident labor, and capacity planning.
Reliability measures should include availability, failed and retried jobs, missed deadlines, mean time to detect and recover, data-quality incidents, recovery-test results, queue delays, and peak concurrency. Compare equivalent business outcomes such as cost per successful pipeline run, terabyte processed, table refreshed, or report delivered.
Keep this Hadoop-specific plan grounded in invoices, usage, incident records, scheduler history, service reports, and a documented normalization method.
A Hadoop-to-Databricks target architecture should show how each operational function will be provided after Hadoop is gone. Product-to-product mappings can hide missing responsibilities for identity, recovery, scheduling, cost allocation, and data lifecycle.
A practical capability map clarifies the intended destination without implying one-to-one equivalence.
The key question is not “Which Databricks feature replaces this Hadoop component?” It is “Which control objective must still be met, by whom, and how will it be tested?”
Resolve architecture boundaries before the pilot. Decide storage locations, regions, encryption keys, managed versus external tables, catalog and schema design, environment isolation, ownership, and retention.
For compute, define runtime baselines, serverless versus classic boundaries, access modes, autoscaling, dependency installation, and exceptions. For orchestration, decide which system owns retries, backfills, calendars, dependency state, and escalation. Networking must cover private connectivity, Domain Name System, egress, cloud endpoints, on-premises routes, and transfer throughput.
A Databricks lakehouse architecture may use bronze, silver, and gold layers, but those layers should represent controlled quality transitions. They are not a mandate to copy every dataset three times.
Name owners for platform, data products, pipelines, identity, network, security, cost, and incident command. Define alerting, escalation, deployment approvals, rollback authority, runtime upgrades, quotas, and support handoffs.
Operational readiness should connect job state, Spark metrics, data-quality results, lineage, audit events, telemetry, and billing. Recovery planning must distinguish rebuilding compute, restoring metadata, replaying pipelines, recovering data, and meeting business objectives.
Before calling the pilot production-representative, require a RACI, runbooks, service-level objectives, dashboards, deployment and restore procedures, a support matrix, cost allocation, and a completed recovery game day.
Each step produces evidence required by the next. A successful notebook run is not an exit criterion.
Choose a pilot that is bounded enough to recover but representative enough to challenge assumptions. Include meaningful data volume, a scheduled transformation, Hive metadata, an external integration, security controls, performance expectations, and a business consumer.
Score candidates on data size, change rate, code diversity, dependencies, schedule complexity, consumers, sensitivity, concurrency, recovery needs, owner engagement, and cutback feasibility. Test one or two high-consequence risks, such as identity mapping, a custom SerDe, or incremental synchronization.
Exit with a pilot charter, source baseline, target design, acceptance plan, rollback plan, cost envelope, and named approvers.
Create repeatable foundations before moving production data: cloud accounts, workspaces, Unity Catalog, storage, identity, networking, encryption, secrets, logging, audit access, and environment separation.
The migration factory should provide repository templates, runtime baselines, compute policies, job templates, test harnesses, reconciliation utilities, tagging, dashboards, runbooks, and evidence storage. Infrastructure as code prevents later waves from depending on manual configuration.
Exit when a clean deployment is reproducible, access is least-privileged, logs are queryable, a sample job can be promoted across environments, and teardown or recovery has been exercised.
Choose HDFS data migration tooling based on cloud, bandwidth, security, file count, change rate, and outage tolerance. Apache DistCp supports distributed copies, while managed services can add agents, scheduling, and monitoring. Changing or open files always require explicit handling.
Where a full recopy cannot fit the cutover window, use bulk transfer followed by controlled incremental synchronization. Keep transfer separate from table conversion. Parquet datasets may be converted in place, rewritten to new Delta locations, or maintained in parallel. The choice depends on rollback, schema cleanup, performance, and coexistence.
Reconcile path counts, bytes, comparable checksums, partitions, row counts, business aggregates, and late changes. Preserve an immutable source checkpoint. Exit when manifests balance, Delta Lake tables pass schema and business tests, lag fits the cutover objective, and rollback can restore the accepted source state.
For a Hive Metastore to Unity Catalog migration, assess table types, locations, formats, SerDes, partitions, views, functions, owners, grants, credentials, and unsupported references before moving metadata. A complete-looking catalog can still fail if files, client behavior, or permissions do not match.
Map databases to catalogs and schemas according to ownership, environment, region, and sharing boundaries. Resolve missing owners, broad grants, service identities, external locations, and managed versus external table choices. Unity Catalog centralizes access control, lineage, auditing, and discovery, but those capabilities depend on deliberate object and identity design.
Databricks Labs UCX can accelerate assessment and parts of a workspace-local Hive Metastore upgrade. Its outputs still require review, testing, and approval.
Exit when critical objects are registered, governed locations are configured, permissions reproduce approved intent, orphaned assets have dispositions, and fallback is explicitly bounded.
When planning Spark workload migration, rehost only where evidence supports limited change. Compare source Spark, Scala, Java, Python, Hive, and Hadoop client versions with the selected Databricks Runtime. Check SQL semantics, data types, error behavior, dependencies, streaming behavior, access modes, and serverless limitations.
Inventory shaded JARs, native code, user-defined functions, custom SerDes, filesystem assumptions, keytabs, init scripts, local disk, checkpoints, and hard-coded YARN settings. Refactor jobs that rely on data locality, mutable HDFS directories, manual partition repair, edge workflows, or implicit scheduler state.
Test deterministic outputs with controlled inputs, plus idempotency, retries, partial failure, backfills, time zones, late data, and duplicate handling. Exit when each workload meets its disposition-specific code, dependency, orchestration, deployment, and support criteria.
Execution is only the start. Functional acceptance should reconcile files, tables, schemas, row counts, key aggregates, business rules, and downstream reports. Where exact equality is inappropriate, document approved tolerances.
Performance tests must use representative data, concurrency, arrival patterns, and cold-start conditions. Compare completion windows, throughput, startup delay, failure rate, and cost per successful outcome. Security acceptance should include positive and negative access tests, privileged roles, service-principal scope, audit visibility, data location, encryption configuration, and separation of duties.
Operational tests should exercise alert routing, failed-task diagnosis, backfill, deployment rollback, credential rotation, capacity failure, and recovery from an injected fault. Exit only with signed evidence from data, workload, security, operations, business, and cost owners.
Group waves by shared data, dependencies, business calendar, owner, security class, and rollback boundary. Before cutover, freeze relevant changes, complete the final synchronization, verify manifests and scheduler state, confirm support coverage, and communicate decision deadlines.
Define measurable rollback triggers, such as reconciliation outside tolerance, missed service windows, access failure, performance regression, or absent visibility. Hypercare needs a time box, enhanced monitoring, and a clear handoff to normal support.
Hadoop retirement comes later. Close schedules, data flows, network routes, service accounts, keytabs, monitoring, backups, archives, support contracts, licenses, infrastructure, and on-call obligations. Exit when no required consumer remains, archival and retention are approved, shutdown has been tested, costs are visibly removed, and benefits are measured against the baseline.
There is no defensible generic duration. A Hadoop to Databricks migration timeline depends on estate size, data volume and change rate, workload dispositions, dependency complexity, test cycles, security approvals, wave design, dual-run requirements, and the planned decommission date. Estimate duration from the estate register and pilot evidence, then reforecast after each wave.
Phase gates convert evidence into spending control. Each gate needs required artifacts, measurable thresholds, decision rights, stop conditions, exception expiry, and a record of who accepted residual risk.
A polished demo should not unlock scale-out if it avoided realistic data, metadata complexity, security, external consumers, recovery, performance, or cost attribution.
Require a pilot scorecard, source baseline, dependency map, architecture decisions, test results, defect log, operating runbook, measured consumption, and rollback evidence. Stop when critical dependencies remain unknown, access is broader than approved, reconciliation is incomplete, or the pilot is materially easier than the next waves.
Set risk-based thresholds for data quality, business-result parity, performance windows, negative access tests, recovery exercises, alert coverage, deployment repeatability, cost variance, and business approval.
The gate pack should include manifests, reconciliation queries, performance comparisons, security records, incident simulations, dashboards, cutover plan, rollback point, and forecast-versus-actual cost. Release authority should span engineering, business, security, operations, and finance.
Require zero scheduled production writes, zero approved readers, no unexplained network flows, no active service accounts, completed archive decisions, and signed owner attestations. Review business intelligence tools, exports, edge nodes, notebooks, integrations, and rare calendar jobs.
Financial closure means contracts are terminated or resized, infrastructure is removed, backup and monitoring charges are eliminated, and support rotations end. Any temporary read-only cluster needs an expiry date, cost owner, and explicit shutdown gate.
A credible Hadoop migration cost model connects workload choices to cash flow. A Databricks migration cost calculator can implement the arithmetic, but the estimate is only as good as its inventory, dispositions, rates, and confidence levels.
Do not blend project spend with recurring operations. Build the model in four layers:
Databricks consumption varies by product, cloud, region, and commercial terms. Use current account-specific prices and actual billing data where available. Do not present a generic list price as total migration cost.
Dual run includes overlapping infrastructure, subscriptions, support, staffing, monitoring, security, incidents, data synchronization, and change coordination. Model it by month and by migration wave.
A useful expression is:
Dual-run penalty = overlapping fixed costs + overlapping variable usage + synchronization and assurance labor + contract timing loss
Delayed shutdown should reduce forecast benefits in the same period. Otherwise, the business case can look healthy while the organisation continues paying for both operating models.
Estimate each wave from observable drivers: datasets, terabytes, file count, daily change, workload count, code size, dependency complexity, disposition, environments, integrations, schedules, security class, recovery tier, test cases, and business approvers.
Rehost is not automatically the cheapest option if data movement, permissions, or testing dominate. Refactoring creates more engineering uncertainty but may reduce steady-state consumption or operational burden. Useful unit measures include cost per accepted workload, terabyte reconciled, successful production run, or legacy dollar retired.
Build low, expected, and high scenarios around transfer throughput, change rate, refactor share, defect rate, test cycles, concurrency, cloud rates, staffing productivity, and decommission delay. Assign ranges to the drivers rather than applying one blanket contingency.
Reforecast after the pilot and each wave. Pause scale-out when cost variance exceeds the agreed threshold without credible corrective action, or when projected benefits depend on an unapproved shutdown date.
A useful Hadoop migration risk register links cause, leading indicator, controls, owner, decision deadline, rollback action, and residual exposure. Generic entries such as “migration risk” do not guide action.
Incomplete transfer, source-target divergence, schema drift, corrupt or open files, unsupported formats, excessive small files, missing partitions, broken views, absent owners, permission drift, lost lineage, and incorrect retention can all undermine acceptance.
Detect them through manifests, HDFS health reports, transfer logs, size or checksum comparisons, row and aggregate reconciliation, schema diffs, partition coverage, access tests, and lineage review. Preserve the accepted source checkpoint and never delete source data because a destination path merely exists.
Unsupported libraries, native dependencies, custom formats, Spark or SQL behavior changes, scheduler gaps, time-zone differences, checkpoint incompatibility, performance regression, and undocumented consumers can delay cutover.
Watch for repeated manual fixes, high exception counts, unexplained result differences, unstable runtimes, and late network discoveries. Use runtime matrices, code scanning, representative load tests, contract tests, scheduler-state tests, and output-to-consumer tracing.
Coexistence can create broader access than either platform intended through duplicated identities, stale keytabs, overlapping grants, unsecured transfer agents, or data placed in an unapproved region.
Apply least privilege, separation of duties, controlled workload identities, encryption, restricted network paths, and auditable approvals. Verify with persona tests, privileged-action logs, service-principal review, location evidence, key rotation, and security sign-off. Platform features alone do not establish compliance.
Unrestricted compute, weak tagging, idle resources, repeated backfills, inefficient file layouts, and missing ownership can increase consumption. Skills gaps often appear after code migration, when teams must operate identity, networking, Unity Catalog, continuous integration and continuous delivery, recovery, and FinOps.
Control these risks with compute policies, budgets, tags, billing dashboards, role-based training, paired delivery, runbooks, and explicit handover criteria. Track unallocated spend, manual interventions, on-call load, and workloads without accountable owners.
Cutover can fail because of uncontrolled source changes, incomplete final synchronization, missed decision deadlines, authentication failure, slow rollback, or unclear communication.
Set freeze windows, final manifests, command-center roles, decision timing, objective rollback triggers, and access to both recovery paths. Run a rollback exercise at representative scale. An untested plan remains an assumption.
Technical completion does not authorize the next wave by itself. The decision should compare agreed thresholds with signed evidence from engineering, business, security, operations, and finance.
Proceed only when:
A conditional go decision must identify the compensating control, risk owner, expiry date, and stop trigger.
Authorize retirement only when:
A Hadoop to Databricks migration is complete only when the target workloads are accepted and the source platform’s dependencies, controls, contracts, and costs are closed.
Trusted by top platforms for our transformative solutions and exceptional results: