 Add as preferred on Google
A Comparative Study of RAG and GraphRAG Using DatabricksRead More
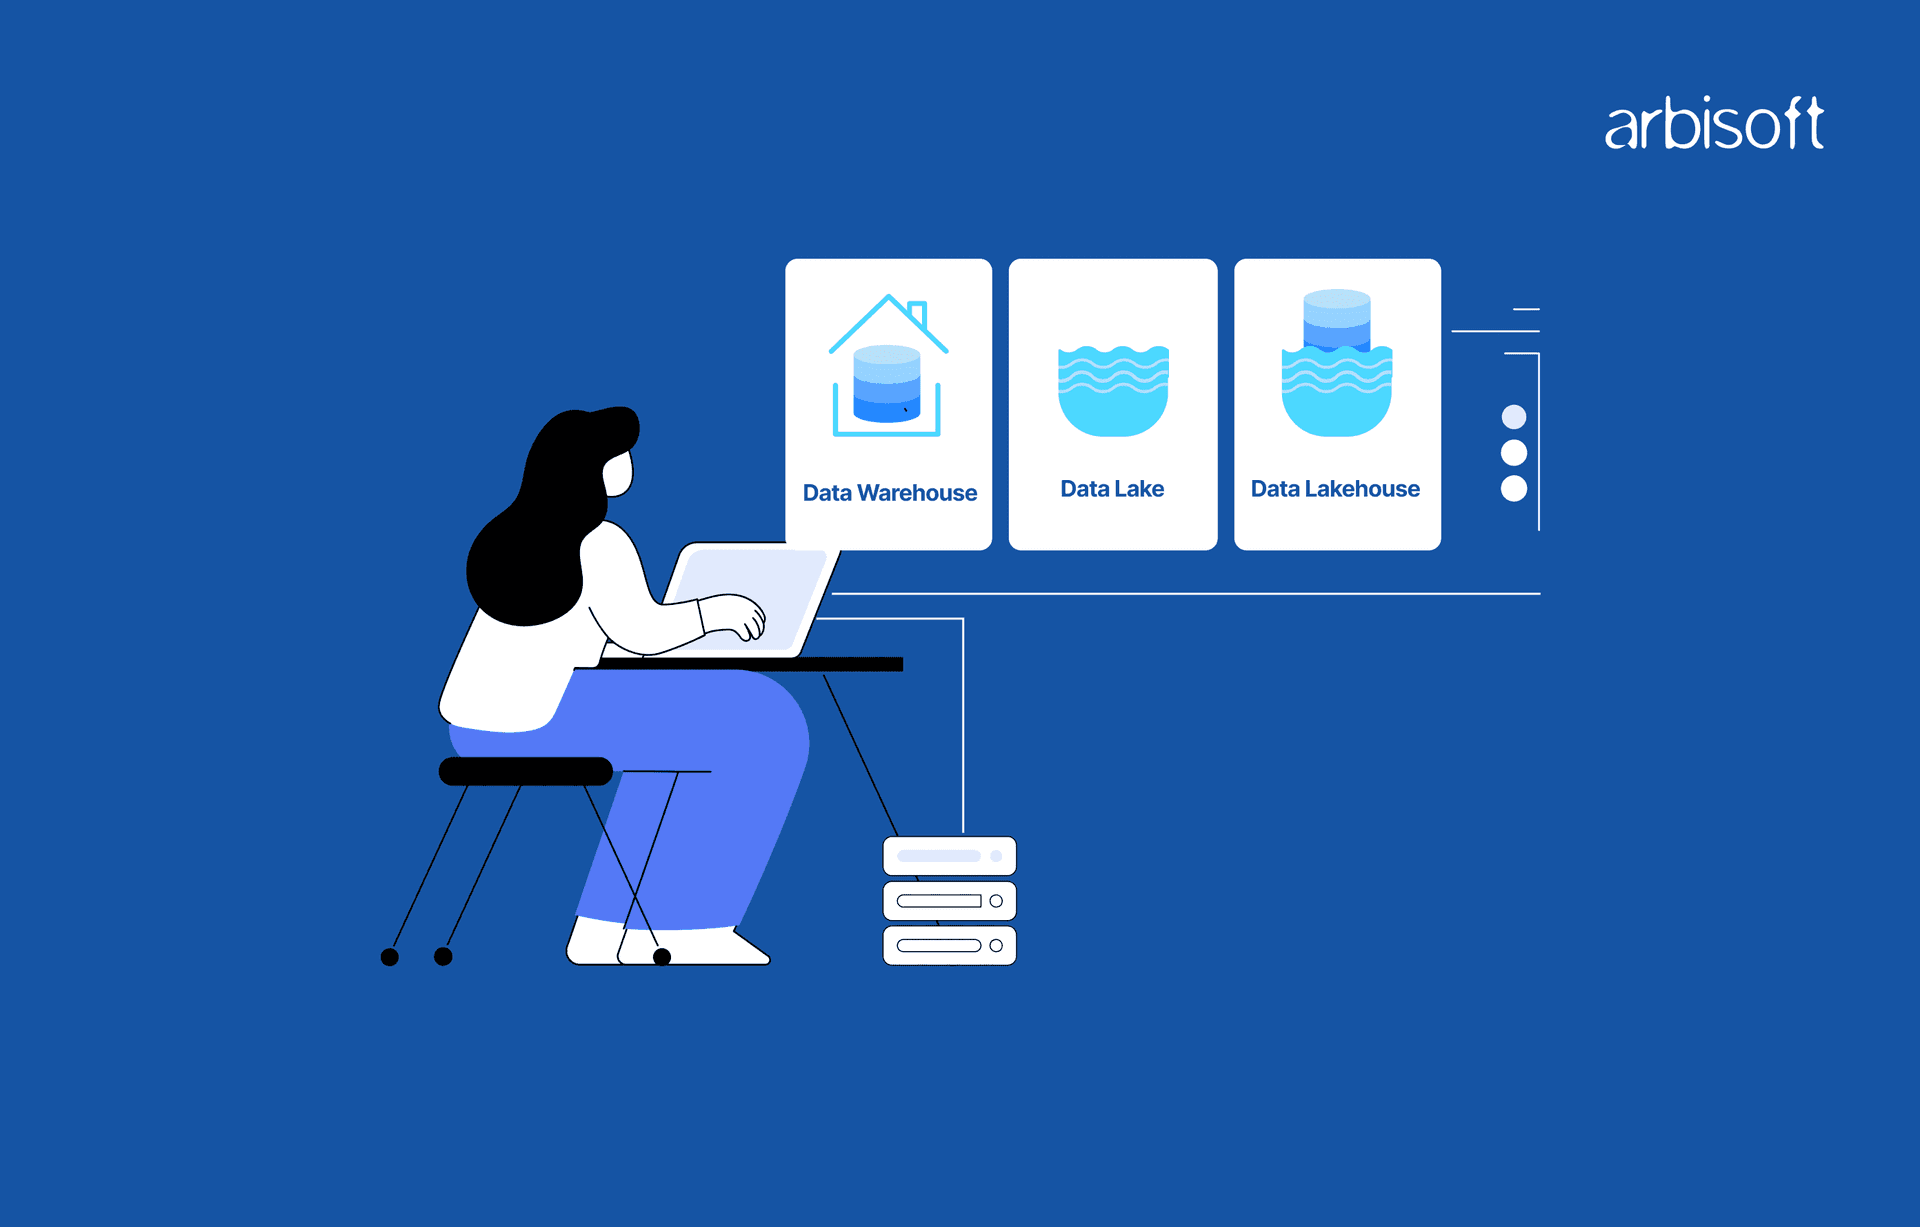
A warehouse suits structured reporting, a lake suits cheap raw storage, and a lakehouse suits teams needing BI and ML on one copy of data.
Compare total monthly cost of one real workload on each option before committing.
Most data teams face this decision once the same customer table sits in three tools and nobody trusts any of them. Data lake vs data lakehouse vs data warehouse is a choice between three ways to organise that data for analytics. They differ in how early they apply structure, which data types they handle well, what they cost to run and how well they support machine learning, and those four points usually settle the choice.
In short, a warehouse suits structured reporting, a lake suits cheap storage of raw and varied data, and a lakehouse adds warehouse-style tables and governance on top of lake storage. This guide compares them side by side and shows where Snowflake and Databricks fit. It ends with a decision rule.
A data warehouse is a central analytical database that holds cleaned, modelled data in tables and answers SQL queries quickly. Structure comes first. The schema is defined before any data is loaded, an approach called schema-on-write, and pipelines transform data from source systems into agreed tables on a schedule before analysts ever query it.
Amazon Redshift, which AWS describes as a fully managed, petabyte-scale data warehouse service, and Snowflake are common cloud examples. In both, the provider runs storage, compute and metadata for you.
A warehouse fits when most data comes from transactional databases and SaaS tools and the main consumers are dashboards, finance reports and other business intelligence work. It also suits teams whose analysts are fluent in SQL but who have little data engineering support.
Fast queries on modelled data are the main strength. Because data is validated on the way in, the same metric returns the same number in every report. Modern warehouses also handle semi-structured data better than older guides suggest. Snowflake's documentation lists JSON, Avro, ORC, Parquet and XML as formats it can import, stored in a flexible VARIANT column type.
Large unstructured workloads fit poorly. Every new source needs modelling before it can be loaded, which slows down experiments with new data. Machine learning teams that need large sets of images, audio or raw event logs for training usually keep them elsewhere and end up with a second copy of related data to secure and keep in sync. Our view is that raw history belongs in cheaper object storage, with only modelled tables kept in the warehouse.
A data lake is low-cost storage, usually cloud object storage such as Amazon S3 or Azure Storage, that keeps data in its original format. Structured tables, JSON files and unstructured files such as images sit side by side. No schema is needed upfront. Structure is applied only when someone reads the data, an approach called schema-on-read.
The Databricks documentation on the lakehouse puts the difference simply: a warehouse delivers clean, structured data for BI, while a lake "permanently and cheaply stores data of any nature in any format."
A lake fits when large volumes of raw data must be kept cheaply and the main users are data engineers and data scientists. Typical contents are clickstream events, application logs, IoT readings, scraped web data and documents kept for future model training.
Low storage cost and format flexibility are the two strengths. Storage is separate from compute, which means processing is paid for only when a job runs. Teams can pick the engine that suits each job, such as Apache Spark for large transformations, and switch engines later without moving the files.
Plain files offer no transactions, no enforced schema and little indexing. Two jobs writing to the same folder can leave half-written results behind, and queries scan far more data than they need because the engine has no table metadata telling it which files to skip. Without a catalog and clear ownership, a lake becomes a data swamp, meaning a pile of files nobody can find or trust. The same Databricks documentation notes that many organisations use lakes for data science and ML but avoid them for BI reporting because the data is unvalidated.
A data lakehouse stores data in open file formats on lake storage and adds a table layer that brings warehouse features to it: ACID transactions, schema enforcement, table versioning and fast SQL. ACID transactions mean a write either completes fully or not at all. Readers never see half-written data. The Databricks documentation defines a lakehouse as "a data management system that combines the benefits of data lakes and data warehouses." The idea was set out in the 2021 CIDR paper "Lakehouse: A New Generation of Open Platforms that Unify Data Warehousing and Advanced Analytics" by Michael Armbrust and colleagues at Databricks, which argued for platforms built on open direct-access data formats with first-class support for machine learning.
The table layer is an open table format. Delta Lake, Apache Iceberg and Apache Hudi are the open table formats that platform documentation names; Google BigQuery, for example, lists support for all three. Many lakehouses refine data in stages before it reaches dashboards, a pattern Databricks calls the medallion architecture.
A lakehouse fits when the same data must feed BI dashboards and ML models, when streaming and batch data need to land in the same tables, or when an existing lake has become hard to trust. It also suits teams that want to keep their data out of any single vendor's storage format.
One copy of the data serves several workloads. Analysts query tables with SQL while data scientists read the same files for training, which removes the nightly copy from lake to warehouse and the arguments about whose numbers are right. Open formats also keep later platform choices open. Snowflake's documentation, for instance, describes Iceberg tables that live in cloud storage the customer manages and that third-party engines can query through a catalog.
A lakehouse hands more design decisions to your team. Someone has to choose a table format and a catalog, schedule maintenance such as compacting small files, and set access policies that hold across every engine reading the data. That is real work. Our view is that a lakehouse built without clear ownership of those tasks drifts back toward a swamp, only with better tooling.
The three architectures differ most on schema, cost, governance and ML support. The table gives the short version, and the sections above give the detail behind each cell.
| Architecture | Schema | Data types | Query performance | Cost profile | Governance and security | AI and ML | Best for |
|---|---|---|---|---|---|---|---|
| Data warehouse | Schema-on-write | Structured, plus semi-structured in modern platforms | Fast SQL on modelled tables | Higher storage cost, predictable for BI | Strong and built into the service | Limited for large raw or unstructured training data | Dashboards, finance and regulatory reporting |
| Data lake | Schema-on-read | Any format, including images and logs | Slower without indexing or table metadata | Lowest storage cost, but engineering time adds up | Weak by default, depends on an added catalog | Good source of raw training data | Cheap raw storage and data science |
| Data lakehouse | Enforced on tables, raw files still allowed | Any format, with tables over open files | Close to warehouse SQL with caching and indexing | Object storage prices plus compute | ACID transactions and a central catalog | Strong, since BI and ML share one copy | Mixed BI and ML on one platform |
Cost needs a closer look than any table can give. A lake's low storage bill can hide the engineer hours spent cleaning data every time it is read, while a warehouse's higher bill often buys less maintenance work for a small team. The fairest comparison is the total monthly cost of one real workload on each option.
Most moves start with a lake that stores everything cheaply but cannot be trusted for reporting, which pushes the team to copy data into a warehouse as well. The 2021 CIDR lakehouse paper named the costs of that two-tier setup: reliability problems, stale data, limited support for advanced analytics and a higher total cost of ownership. Four drivers come up most often.
One example appears among the projects on Arbisoft's Databricks services page. A global media company serving more than 100 million monthly visitors moved to Databricks to simplify a fragmented data stack and deliver personalised recommendations across channels. The page reports 2,000 ML models running in production, 2 million recommendations served daily and $6 million saved in IT costs.
A move pays off when the lake's problem is trust or duplication. In our view, a lake used only by a small data science team, with no reporting on top, gains little from conversion.
Snowflake and Databricks now both cover warehouse and lakehouse workloads. They start from opposite ends.
Snowflake is a cloud data warehouse platform. Its documentation describes Apache Iceberg tables that combine the performance and query semantics of standard Snowflake tables with external cloud storage the customer manages, plus catalog integrations that can read Delta and Parquet files or connect to Unity Catalog in Databricks. A Snowflake team can therefore adopt open lakehouse storage without leaving the platform.
Databricks built its platform around the lakehouse, with Delta Lake as the storage layer and Unity Catalog for governance of data and AI. Its documentation states that data warehousing on Databricks runs on the lakehouse and Databricks SQL. Teams with heavy data engineering, streaming or ML work usually find Databricks the more natural starting point.
Some teams run both platforms. Our guide to when Databricks and Snowflake work better together covers that pattern, and our comparison of Databricks vs traditional data warehousing goes deeper into streaming, CDC and governance differences.
The right architecture follows from your data types, main workloads, governance needs and team skills. Work through these questions in order and stop at the first one that matches.
Our view is that a warehouse plus a lakehouse is a sensible end state for many mid-market companies. No single architecture wins every workload. Platform features now overlap enough that two engines sharing one copy of data in an open format is a practical design, and that design keeps later platform changes cheaper than a full migration.
The 2021 CIDR paper predicted that the traditional warehouse architecture would wither, but warehouses are still widely used for BI, so the lakehouse is replacing them only in part. The bigger change is overlap. Snowflake now supports Iceberg tables, and Databricks offers SQL warehousing on its lakehouse. The two categories are converging.
To a limited degree. Snowflake supports unstructured files in internal and external stages and handles semi-structured formats such as JSON and XML. Large image or audio sets for model training still sit more naturally in object storage.
A lakehouse does not need a separate lake first, because it runs on lake storage and building one creates that storage layer at the same time. Teams with an existing lake can convert Parquet data into Delta Lake tables in place, which avoids copying files and is usually the quickest path to a working lakehouse.
It can be, depending on the workload. Lakehouse data sits in object storage, which is often cheaper per terabyte than warehouse storage. Compute, engineering time and maintenance such as file compaction add to the bill, though. For a small team running mostly dashboards, a managed warehouse can cost less overall, so test one real workload on both before deciding.
A data swamp is a data lake that has lost its value because nobody catalogued or owned the data going into it. Files pile up with unclear schemas and duplicates, and analysts stop trusting them. A catalog with named owners and tables with enforced schemas prevent it.
If the data lake vs data lakehouse vs data warehouse decision rule points to a lakehouse or a hybrid, start with one workload that serves both BI and ML, then measure the effort and cost before moving anything else. That first workload shows whether the table format, catalog and team skills are ready. Arbisoft's data engineering services cover data pipelines, warehousing that centralises fragmented data into a single source of truth, governance and data lake setup, which is the work a first lakehouse or hybrid workload needs.
...Loading Related Blogs
Trusted by top platforms for our transformative solutions and exceptional results: