 Add as preferred on Google
EdTech Platform Types ExplainedRead More
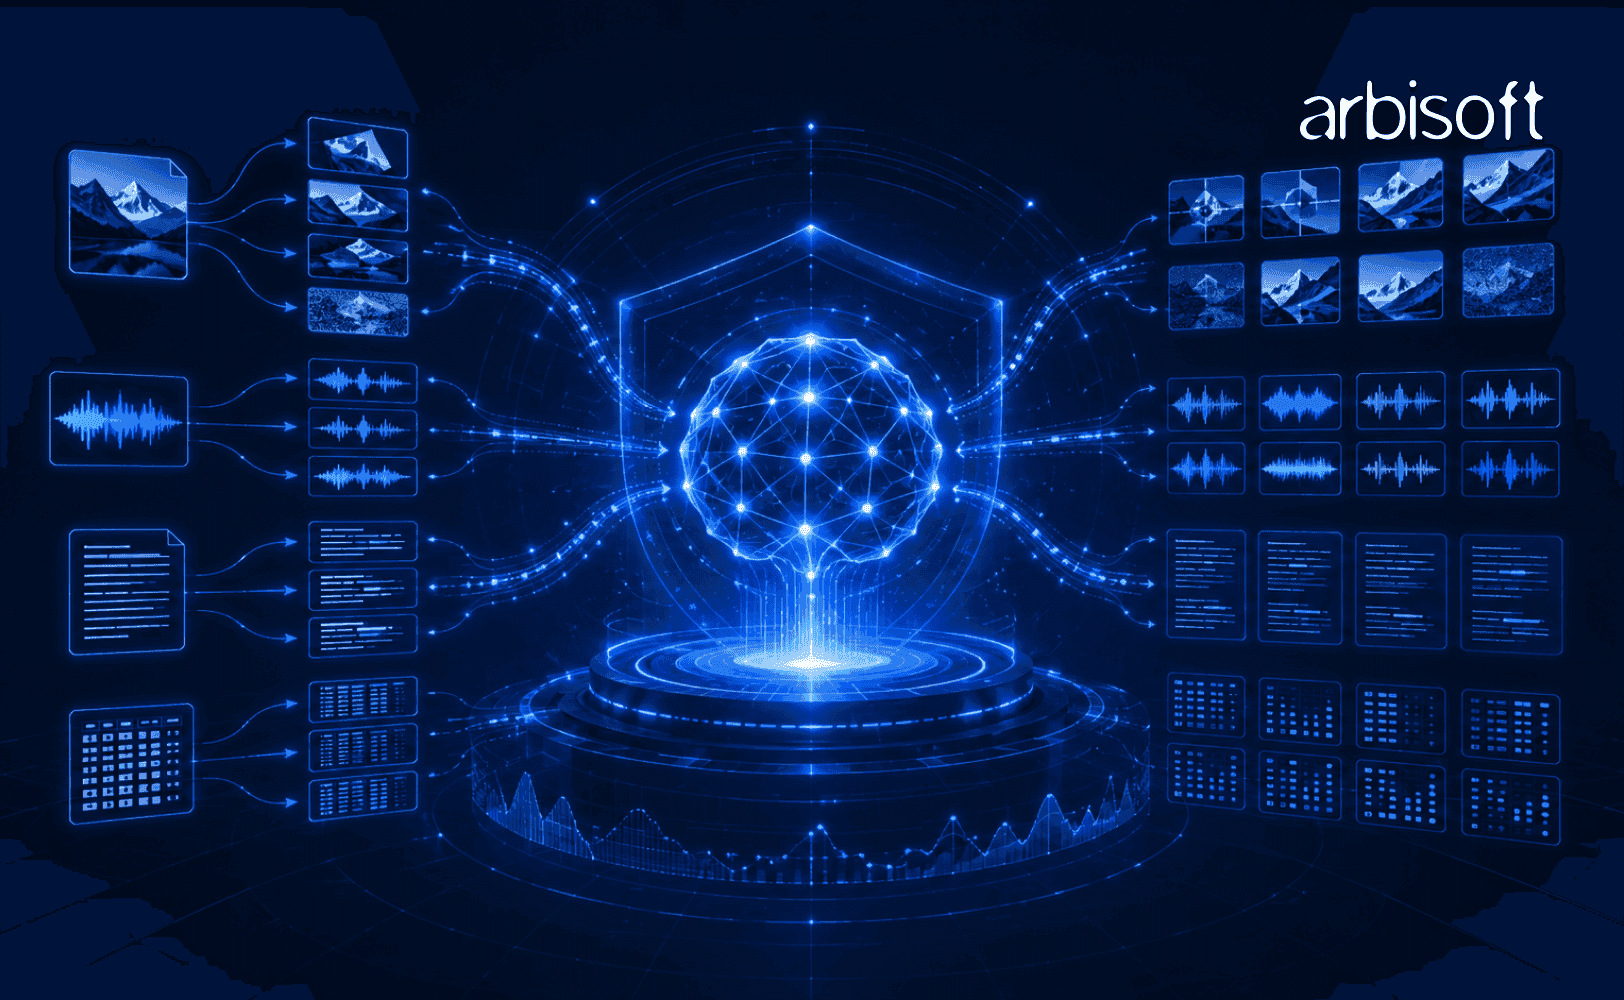
Data augmentation is the practice of creating additional training examples by modifying existing data in ways that preserve the underlying meaning or label.
Model robustness means a model continues to perform reliably when the input data changes, becomes noisy, contains edge cases, or comes from conditions that were not perfectly represented in training.
This article explains why data augmentation matters, what model robustness really means, and how to use augmentation techniques to make models more dependable in real-world settings.
Use this article as a practical reference when you are training, evaluating, or hardening a machine learning system.
Data augmentation is one of the most practical ways to improve model robustness because it helps a model learn from more varied examples without requiring a proportional increase in manually labeled data.
That matters because production data is rarely clean, stable, or complete. Images may be rotated or blurred. Text may contain typos, paraphrases, slang, or domain-specific phrasing. Audio may have background noise. Tabular data may contain missing values, class imbalance, or shifted distributions. A model trained only on idealized examples often works well in the lab and fails when reality becomes messy.
The goal of augmentation is not to make the training set bigger for its own sake. The goal is to expose the model to realistic variations so that it learns stable patterns instead of overfitting to incidental details.
In practical terms, model robustness means the system can keep performing when the world is imperfect. A robust model is not necessarily the one with the highest score on a single benchmark. It is the one that keeps behaving sensibly when conditions change, inputs are noisy, or edge cases appear.
The key lesson is simple: if you want a model to survive production variability, you must train it on variability.
Data augmentation is sometimes described too casually as “making copies of data with changes.” That is directionally correct, but incomplete.
The important idea is that the transformation must preserve the semantic target. If the label changes after the transformation, the augmentation is invalid or needs relabeling.
For example:
That distinction is critical. Good augmentation is not random corruption. It is controlled variation.
We need augmentation because training data is almost always incomplete relative to the diversity of production data.
The main reasons are predictable:
Models encounter lighting changes, camera angles, spelling variation, accents, device differences, seasonal effects, and behavior drift. Training on a narrow slice of reality creates brittle models.
In many domains, high-quality labels require domain experts, review processes, or user feedback loops. Augmentation expands coverage without requiring the same level of new manual annotation for every example.
When a model sees too many near-identical examples, it can memorize surface patterns instead of learning durable structure. Augmentation introduces controlled diversity that reduces that risk.
Production failures often come from edge cases rather than common cases. Augmentation can help simulate rare but important conditions such as low light, noisy text, class imbalance, or unusual phrasing.
The data you train on is not the data you will always receive. Augmentation is one way to prepare the model for that shift before the shift becomes a production incident.
Model robustness is the ability of a model to maintain useful behavior when conditions vary.
That variation may come from:
A robust model does not need to be perfect under every condition. It needs to degrade gracefully rather than fail abruptly.
In practice, robustness usually includes several dimensions:
Targeting model robustness means designing, training, and evaluating the system so that reliability under variation is a first-class objective.
That is different from simply optimizing for one aggregate metric on a static validation set.
If you target robustness, you ask different questions:
This shifts the mindset from “Can the model score well?” to “Can the model be trusted in the conditions it will actually face?”
For many teams, robustness is not about squeezing out another point of accuracy. It is about reducing the cost of failure.
Different data types need different augmentation strategies. A method that works well for images may be useless or harmful for text or tabular records.
Big data augmentation is not usually a separate data modality. It is the practice of applying augmentation at scale across very large datasets, often with distributed pipelines, streaming jobs, or offline batch processing.
This matters when the dataset is too large for manual inspection and too valuable to process casually. In those cases, augmentation must be operationally efficient as well as statistically useful.
Common concerns include:
The key idea is that scale changes the operating problem. The augmentation logic may be the same, but the way you produce, store, validate, and monitor augmented data must be much more disciplined.
For example, in large retail, ad-tech, or platform telemetry systems, augmentation may involve balancing rare events, synthesizing additional examples for minority segments, or generating perturbations across billions of records. The robustness benefit is still the same, but the implementation must be engineered for volume.
Video data augmentation is a natural extension of image augmentation, but it is more complex because the model must preserve both spatial content and temporal consistency.
Common techniques include:
Video augmentation is useful for action recognition, event detection, surveillance analytics, sports analysis, robotics, and any task where the same event may appear from different angles, speeds, or capture conditions.
The important constraint is temporal realism. A transformation that looks acceptable on a single frame may break the meaning of the video if it disrupts the sequence in a way that changes the action label.
For example, speeding up or reversing a clip may be valid in one task and invalid in another. The augmentation must match the semantics of the target label.
IoT data augmentation is especially relevant for sensor-heavy systems such as manufacturing, smart buildings, healthcare devices, logistics, and connected hardware platforms.
IoT data often looks like time series, but it can also include event streams, multivariate sensor readings, device metadata, and environmental context.
Useful techniques include:
This kind of augmentation helps models become more robust to sensor drift, packet loss, calibration differences, hardware variability, and environmental noise.
The main challenge is realism. Sensor augmentation must respect physical constraints. If the transformed data violates the underlying process, the model may learn patterns that do not exist in the real system.
Image augmentation is the most familiar category.
Common techniques include:
These techniques help a vision model become less sensitive to camera angle, framing, illumination, and minor image defects.
Use them carefully. A left-right flip is useful for many object recognition tasks, but it can be wrong for text, medical imaging, or any task where orientation carries meaning.
Text augmentation is more subtle because meaning can change with very small edits.
Common techniques include:
Text augmentation is useful for classification, retrieval, and intent detection, but it must respect domain meaning. Replacing a keyword with a synonym can break legal, medical, or technical text if the substitute is not exact.
In text tasks, preserving the label is often harder than generating the variation.
For speech and audio models, useful techniques include:
These methods help the model handle real recording conditions such as microphones, echo, crowd noise, and different speaking styles.
Tabular augmentation is often less obvious, but still important.
Possible techniques include:
The challenge here is preserving realistic relationships between features. Tabular augmentation can easily create impossible records if domain constraints are ignored.
For forecasting, anomaly detection, and signal analysis, common techniques include:
These techniques help models learn temporal patterns that are not tied to one exact timeline.
Synthetic data is a broader category that may use rules, simulations, or generative models to create new examples.
It can be useful when:
But synthetic data is not automatically better than real data. It must be validated for realism, label quality, and downstream utility.
The best augmentation strategy depends on the failure modes you want to reduce.
If users submit blurry images, augment with blur. If users write messy text, augment with paraphrases and typos. If sensors drift, augment with noise and scaling.
The most effective augmentation is usually the one that simulates actual deployment conditions.
More augmentation is not always better.
If the transformed example no longer resembles a valid input, the model may learn the wrong invariances. The result can be worse performance, not better robustness.
When the problem is class imbalance, augmentation can help minority classes appear more often.
That said, oversampling should not create a false sense of diversity. If every synthetic minority example is nearly identical, the model may still overfit.
If you know where the model fails, use those cases as part of the augmentation or retraining loop.
This approach is powerful because it focuses training on the edge cases that matter most.
Some augmentation is best applied offline during dataset preparation. Other augmentation is better done on the fly during training.
On-the-fly augmentation can reduce storage cost and increase variety. Offline augmentation can be easier to audit and reproduce.
Augmentation improves robustness because it changes what the model learns to rely on.
Without augmentation, a model may latch onto shortcuts:
With good augmentation, the model is more likely to learn invariant features that survive small changes.
That does not mean augmentation magically creates robustness. It means the model sees enough variation during training that it is less surprised later.
Data augmentation is useful, but it can also be misused.
Common failure patterns include:
If augmentation changes the meaning of the data, it becomes data corruption rather than data enhancement.
You cannot assume the model is more robust just because the training pipeline got more complex.
Useful evaluation methods include:
Check whether augmentation preserved or improved baseline accuracy on normal test data.
Create test sets with noise, blur, paraphrases, missing values, or other realistic perturbations.
Measure performance across subgroups, environments, device types, classes, and edge cases.
Look at the weakest segments, not just the average score.
A robust model should not only be accurate; it should also know when it is uncertain.
Compare performance across model versions so that robustness does not quietly degrade over time.
The main principle is simple: robustness must be measured under conditions that resemble reality.
Augmentation tends to be especially effective when:
It is less effective when the data itself is fundamentally wrong, the labels are inconsistent, or the problem requires more representative collection rather than more transformation.
Leaders do not need to design augmentation code, but they should ask for evidence that robustness is being treated seriously.
Useful questions include:
If these questions cannot be answered clearly, the model may be accurate in testing but fragile in production.
Engineering teams should treat augmentation and robustness as part of the training system, not as an afterthought.
Minimum implementation checklist:
If augmentation is generated by code or a model, also include:
A simple operating model for robustness improvement looks like this:
This loop matters because robustness is not a one-time property. It is something you build, test, and maintain.
Data augmentation is valuable because it teaches the model about variation before that variation appears in production.
Model robustness is the practical outcome you want: a system that keeps working when the real world is noisy, incomplete, or slightly different from the training set.
Targeting robustness means making resilience an explicit objective, not an accidental byproduct. That requires matching augmentation to real failure modes, preserving semantic correctness, measuring stress performance, and monitoring the model after release.
If you do that well, the model becomes less fragile and more trustworthy. If you do it poorly, augmentation can add volume without adding resilience.
If you want to continue the series, the natural next article is a deeper guide on evaluating robustness, building stress tests, and detecting distribution shift before it becomes a production problem.
Trusted by top platforms for our transformative solutions and exceptional results: