 Add as preferred on Google
How to Scale an EdTech Platform to Millions of LearnersRead More
Most EdTech products don’t run into trouble because the learner experience is too ambitious. The harder part is usually everything happening behind it. A clean learner dashboard might look like the main product, but it is only one piece of a system that may also need organizational structures, bulk enrollments, different admin roles, and custom setups for each customer. That behind-the-scenes work is often where the real complexity, time, and cost start to add up.
Education makes that gap wider, because scale arrives as assessment windows where thousands of learners submit inside the same hour rather than as a smooth curve. Interoperability is specified rather than negotiated, through 1EdTech's LTI 1.3 and LTI Advantage, OneRoster for rostering, and QTI for assessment items, while corporate learning still runs on SCORM alongside xAPI 2.0, now published as IEEE 9274.1.1-2023. Accessibility acts as a procurement gate for public institutions, measured against WCAG 2.2, a W3C Recommendation since October 2023. Each shapes the architecture before a learner screen exists.
This is a decision-first guide to enterprise EdTech development, covering what the work spans beyond a learning platform and how to scope it around roles, customer structures, existing systems, and data. It then works through building, buying, extending, integrating, or modernizing, the architecture enterprise deployment demands, and what moves cost and timeline. The question it settles is whether the next investment belongs in custom EdTech software, an extended platform, an integration layer, or modernization. Written for CTOs, product leaders, and heads of learning at EdTech companies, corporate L&D teams, and institutions weighing an enterprise EdTech development company.
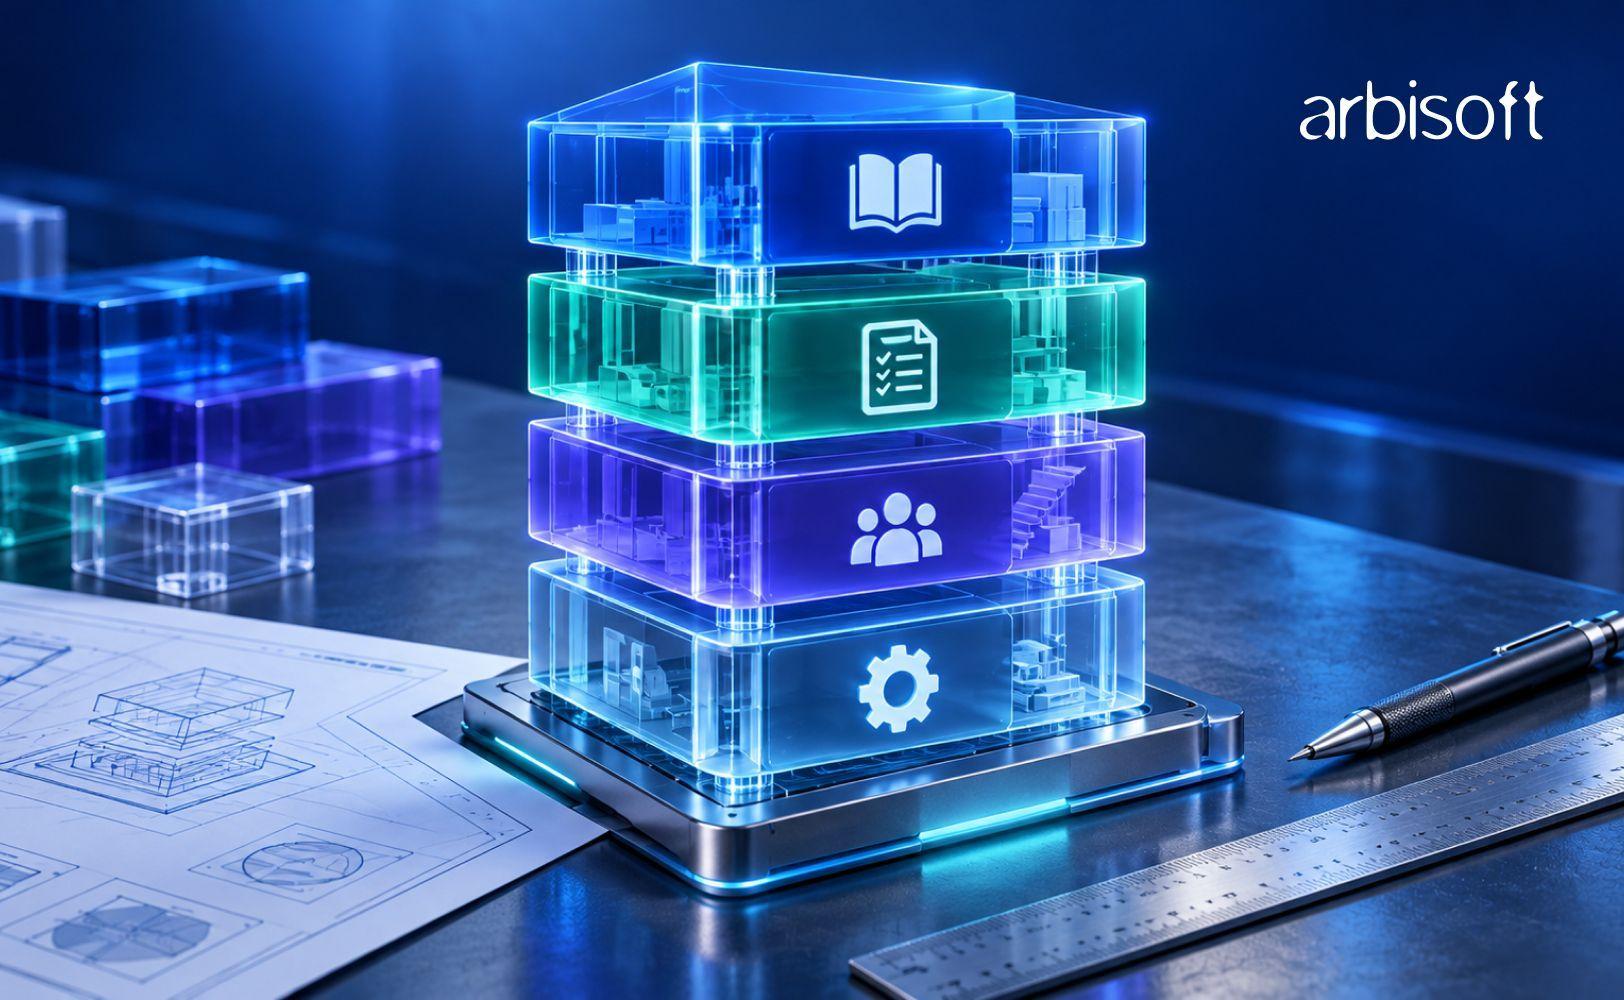
Enterprise EdTech development is the engineering of a complete education product and the environment it runs in: the learner experience, the workflows around it, the administration that keeps it running, the systems it connects to, the data it produces, and the infrastructure underneath. A learning platform is one component of that, often not the largest.
The work spans recognizable layers:
The line that matters most runs between learner-facing software and the operational infrastructure behind it. A polished learner dashboard can turn out to be a small share of the system once administrators also need organizational hierarchies, permissions, bulk enrollment, exception handling, per-customer configuration, reporting, and support tooling. Teams that scope only what the learner sees find the rest halfway through the build, at the point where it costs the most to add.
Two organizations can build the same category of product and end up with programs of work that differ by years. The learning and operating model underneath sets the size of the job.
How learning happens, and how the operation around it runs, should decide which capabilities the product needs. Those capabilities decide the architecture, and the architecture decides the development effort. A feature list written before that chain is worked out usually describes the smallest part of the system.
Different learning models generate different engineering requirements. A self-paced consumer course product needs modest role logic, simple enrollment, and content delivery that performs. A compliance-driven corporate training platform sold to enterprises needs tenant-level administration, client managers, learner groups, rule-based assignment, certification renewal, customer-specific reporting, enterprise identity, and HRIS integration. In a screenshot, the two learner interfaces can look almost identical. The systems behind them are not comparable in cost or operating burden.
Live instruction changes the shape again. Tutoring and cohort programs bring scheduling, capacity limits, cancellation rules, session recording, and sometimes real-time infrastructure. Adaptive and assessment-driven learning pushes the difficulty into content modeling, item banks, and scoring logic.
Four questions settle most of it.
List every role first: learners, instructors, tutors, internal administrators, institutional administrators, client managers, support staff, partners, and finance or operations users. Each one carries permissions, workflows, reporting needs, and a boundary around the data it can see.
Role design is where hidden scope lives. A support team that cannot safely impersonate a learner escalates every issue to engineering. A client administrator who cannot fix a mis-assigned enrollment files a ticket that somebody then resolves by hand.
Decide early whether the system serves individual users, institutions, enterprises with departments and regions, campuses, cohorts, or client organizations with sub-structures of their own. These relationships sit at the center of the data model, and they become painful to change once customer data exists.
The consequences are commercial. Weak tenant structure means every enterprise customer needs manual setup, bespoke data segmentation, and custom reporting. Growth then adds engineering overhead in place of repeatable onboarding, and margin disappears into implementation work.
Most enterprises do not lack technology. They already run an LMS, an SIS or HRIS, a CRM, an ERP, an identity provider, payment systems, content repositories, video platforms, assessment tools, and internal applications nobody wants to touch. Fragmentation is the problem. The most useful project is sometimes a connective layer that makes those existing systems behave as one workflow.
Reporting, compliance records, learner progression, certification status, alerts, customer-facing analytics, and administrative automation each carry architectural consequences. Work out what the organization has to prove, to whom, and how often. An annual audit export and a live analytics product are different systems, even when both arrive in the backlog as "reporting."
EdTech development does not automatically mean a new platform. Five approaches cover most enterprise situations, and the right one depends on where the differentiation actually lives.
Custom development fits when the learning model, workflow, business model, or integration profile falls outside what existing products support, or when the software itself is what the organization competes on. Ownership is the trade-off. More control over the product comes with full responsibility for architecture, security, scaling, and maintenance.
Buying fits when requirements are standard and the organization competes on content, instruction, or service. Feature coverage on day one is the easy part to check. The constraints worth evaluating during selection are the future ones: extensibility, API quality, data export, tenancy limits, and what happens when a large customer asks for something the vendor roadmap does not include.
Many organizations use a commercial or open-source platform as a foundation and build their differentiating capability around it. This is often the fastest route to a defensible product, and it needs discipline about one distinction. Configuration changes behavior through supported settings and survives upgrades. Customization changes the platform itself and becomes yours to maintain through every version change.
When the individual systems work and the process does not, the engineering problem is orchestration. A corporate learning workflow shows the shape of it. An employee record is created in the HRIS. Role-based training is assigned. The manager tracks progress. A certification approaches expiry, retraining is triggered, and the compliance record updates. Almost none of that is learner-facing. Most of it is event handling, data mapping, identity, and error recovery across systems that were never designed to cooperate.
Modernization applies when the product has value and the architecture limits it: slow releases, brittle integrations, performance ceilings, infrastructure that cannot meet enterprise demand, a data model that cannot support analytics or AI. The work can be incremental. Isolating a bottleneck, extracting a service, or rebuilding the data model often returns more value at lower risk than a rewrite.
| Situation | Likely approach | Core trade-off |
| Product or workflow is the differentiation | Build custom | More flexibility, more engineering ownership |
| Requirement is standard and well served | Buy and configure | Faster adoption, platform constraints |
| Good platform, missing differentiating capability | Extend or customize | Build on the foundation, own the customization |
| Capable systems, broken end-to-end workflow | Integrate | Preserve investment, solve fragmentation |
| Valuable product constrained by architecture | Modernize | Reduce technical risk without rebuilding indiscriminately |
These are decision patterns rather than rules. Large programs usually combine several of them: extend the LMS, integrate the HRIS, build the assessment product, modernize reporting.
Whichever approach is chosen, enterprise deployment imposes requirements that a prototype or a single-customer application never meets.
Enterprise systems usually have to represent customers or institutions, departments, administrators, managers, instructors, learners, and sometimes external partners. Four decisions follow: how tenant data is isolated, how much administration is delegated to the customer, which configuration is per-tenant, and how visibility is scoped across a hierarchy. Get them right and onboarding an institution becomes a configuration exercise. Get them wrong and every customer becomes a project.
Integrations belong in the architecture from the start. Enterprise buyers expect learner data to flow from the SIS or HRIS, results to reach their reporting systems, and content or tools to work inside the platforms they already run.
Education has established interoperability standards worth evaluating against the actual use case. 1EdTech maintains LTI, where LTI 1.3 and the LTI Advantage package cover single sign-on launch, deep linking, assignment and grade services, and names and roles provisioning, alongside OneRoster for rostering and gradebook exchange and QTI for assessment items. SCORM remains widely deployed in corporate learning, while xAPI has moved on, with xAPI 2.0 published as IEEE 9274.1.1-2023. Check versions and conformance claims against the specifications before they go into a contract.
Enterprise and institutional customers will ask for SSO against their own identity provider, role-based access control, delegated administration, and lifecycle handling so access changes when someone joins, moves, or leaves. Identity retrofitted late forces rework in the permission model and in every screen that depends on it.
Scale in EdTech rarely arrives as a smooth curve. It arrives as assessment windows where thousands of learners submit inside the same hour, semester and onboarding peaks, media workloads, heavy reporting queries, background processing for enrollment and certification, bulk integration syncs, and regional deployment where data residency applies. Design against the peaks the operating model actually produces, with the resilience and deployment practices needed to survive them.
Recording learner activity and designing data that can answer questions are two different jobs. Product analytics, learner progress, institutional and customer reporting, recommendations, AI features, and compliance evidence each make their own demands on the model. Reporting requirements discovered late are among the most reliable sources of rework, because they send the team back to the data model, the event capture, and the permission layer at the same time.
Enterprise customers notice outages during assessment windows. Teams need monitoring, structured logging, alerting, traceable integration failures, reliable deployments, and enough visibility for support staff to diagnose a problem without pulling in an engineer. Integrations need retry, reconciliation, and a view of what did not sync.
These four areas decide whether a product can be deployed inside an institution or an enterprise at all, and each one gets expensive when it arrives late.
Security work here centers on access control, tenant isolation, protection of learner data, auditability, integration credentials, permission lifecycle, and secure development and operations practice. Legal obligations vary by jurisdiction, sector, learner age, and customer type. Establish them with counsel and against current regulatory sources, not a generic checklist.
Accessibility is a product requirement and a procurement gate, particularly for public institutions. WCAG is the reference standard, and WCAG 2.2 became a W3C Recommendation in October 2023, with W3C advising organizations to work to the most current version when setting policy. Confirm which version and conformance level a buyer requires. Building against it from the start costs far less than retrofitting an interface and its component library after an audit.
Data governance is worth settling before the architecture is fixed: who owns the data, which system is authoritative for each entity, who can access what, how long records are retained, how data moves between systems, and what happens when a learner, employee, or customer leaves.
AI sits inside this environment as one capability among others. Useful applications include tutoring support, instructor and administrator copilots, recommendations, semantic search across content, assessment assistance, and operational automation. The engineering questions behind them carry more weight than the choice of model: whether the underlying data is usable, what content the system is allowed to reach, how permissions and tenant boundaries survive retrieval, how outputs are evaluated, where a human stays in the loop, and how quality, cost, and sensitive information are handled. Calling a model API is an implementation detail.
A useful scoping process answers questions in order, because the later answers depend on the earlier ones:
Separate the resulting requirements into learner-facing, administrative, customer-facing, integration, infrastructure, analytics, and support categories. Most estimates go wrong because only the first category gets written down in detail.
The chain worth mapping runs in one direction: learning model, workflows, users and roles, product capabilities, integrations and data, architecture, development effort. Each link constrains the next, and a backlog written without the chain looks reasonable while hiding most of the work.
"Reporting" shows how much can hide inside a single backlog entry. In one product it is three dashboards over a single database. In another it is per-tenant reporting across roles and permissions, blended with external HR data, exportable on a schedule, and still accurate after an organizational restructure. Same word, different systems entirely.
Cost and timeline follow complexity, and complexity does not track the product category. The drivers that move them most: the number and depth of user roles, multi-tenancy and per-customer configuration, learning model and assessment logic, content and media workflows, real-time functionality, mobile scope, the number and quality of integrations, identity and SSO requirements, legacy constraints, migration volume and data quality, reporting depth, AI components, accessibility and security requirements, regional deployment, existing technical debt, and the QA and release complexity all of it creates.
Two products that share the name "corporate learning platform" show the spread. One serves a single internal workforce with one identity provider, one organizational structure, and one reporting audience. The other serves many enterprise customers, each with its own administrators, SSO configuration, branding, hierarchy, integrations, and compliance reporting. The second carries a different architecture and a different operating model, with onboarding and support functions attached.
Overruns come from a short list of recurring causes:
Industry familiarity is a weak qualifying criterion on its own. The right EdTech development partner matches the engineering problem you have: greenfield product work, platform extension, integration and orchestration, modernization, data and AI, or a combination.
Worth testing during evaluation:
Ask for evidence that maps to your situation: comparable systems, technical detail instead of screenshots, references from engagements that continued past launch, and examples of operating at the scale you expect.
Get internal agreement on these before committing to a backlog or a vendor:
Answers that span product design, architecture, integrations, data, modernization, or AI point to a technical scoping conversation ahead of a feature list and a delivery estimate. It is worth having before budget is committed.
No. An LMS is a product category with built-in assumptions about courses, enrollment, and reporting. A custom platform is built around a specific learning and operating model. Many organizations run both: an LMS for standard delivery, custom software for what defines their product.
Usually. Modernization is often a sequence of contained changes: extracting a bottleneck into a service, replacing an integration layer, rebuilding the data model behind reporting, moving infrastructure. A rewrite is justified when the architecture cannot support the required operating model at all, and that should be an evidenced conclusion rather than a starting assumption.
Trusted by top platforms for our transformative solutions and exceptional results: